Dedicated Model Inference
Deploy models on dedicated infrastructure, engineered for speed
Purpose-built for teams who need control and the best economics in the market.
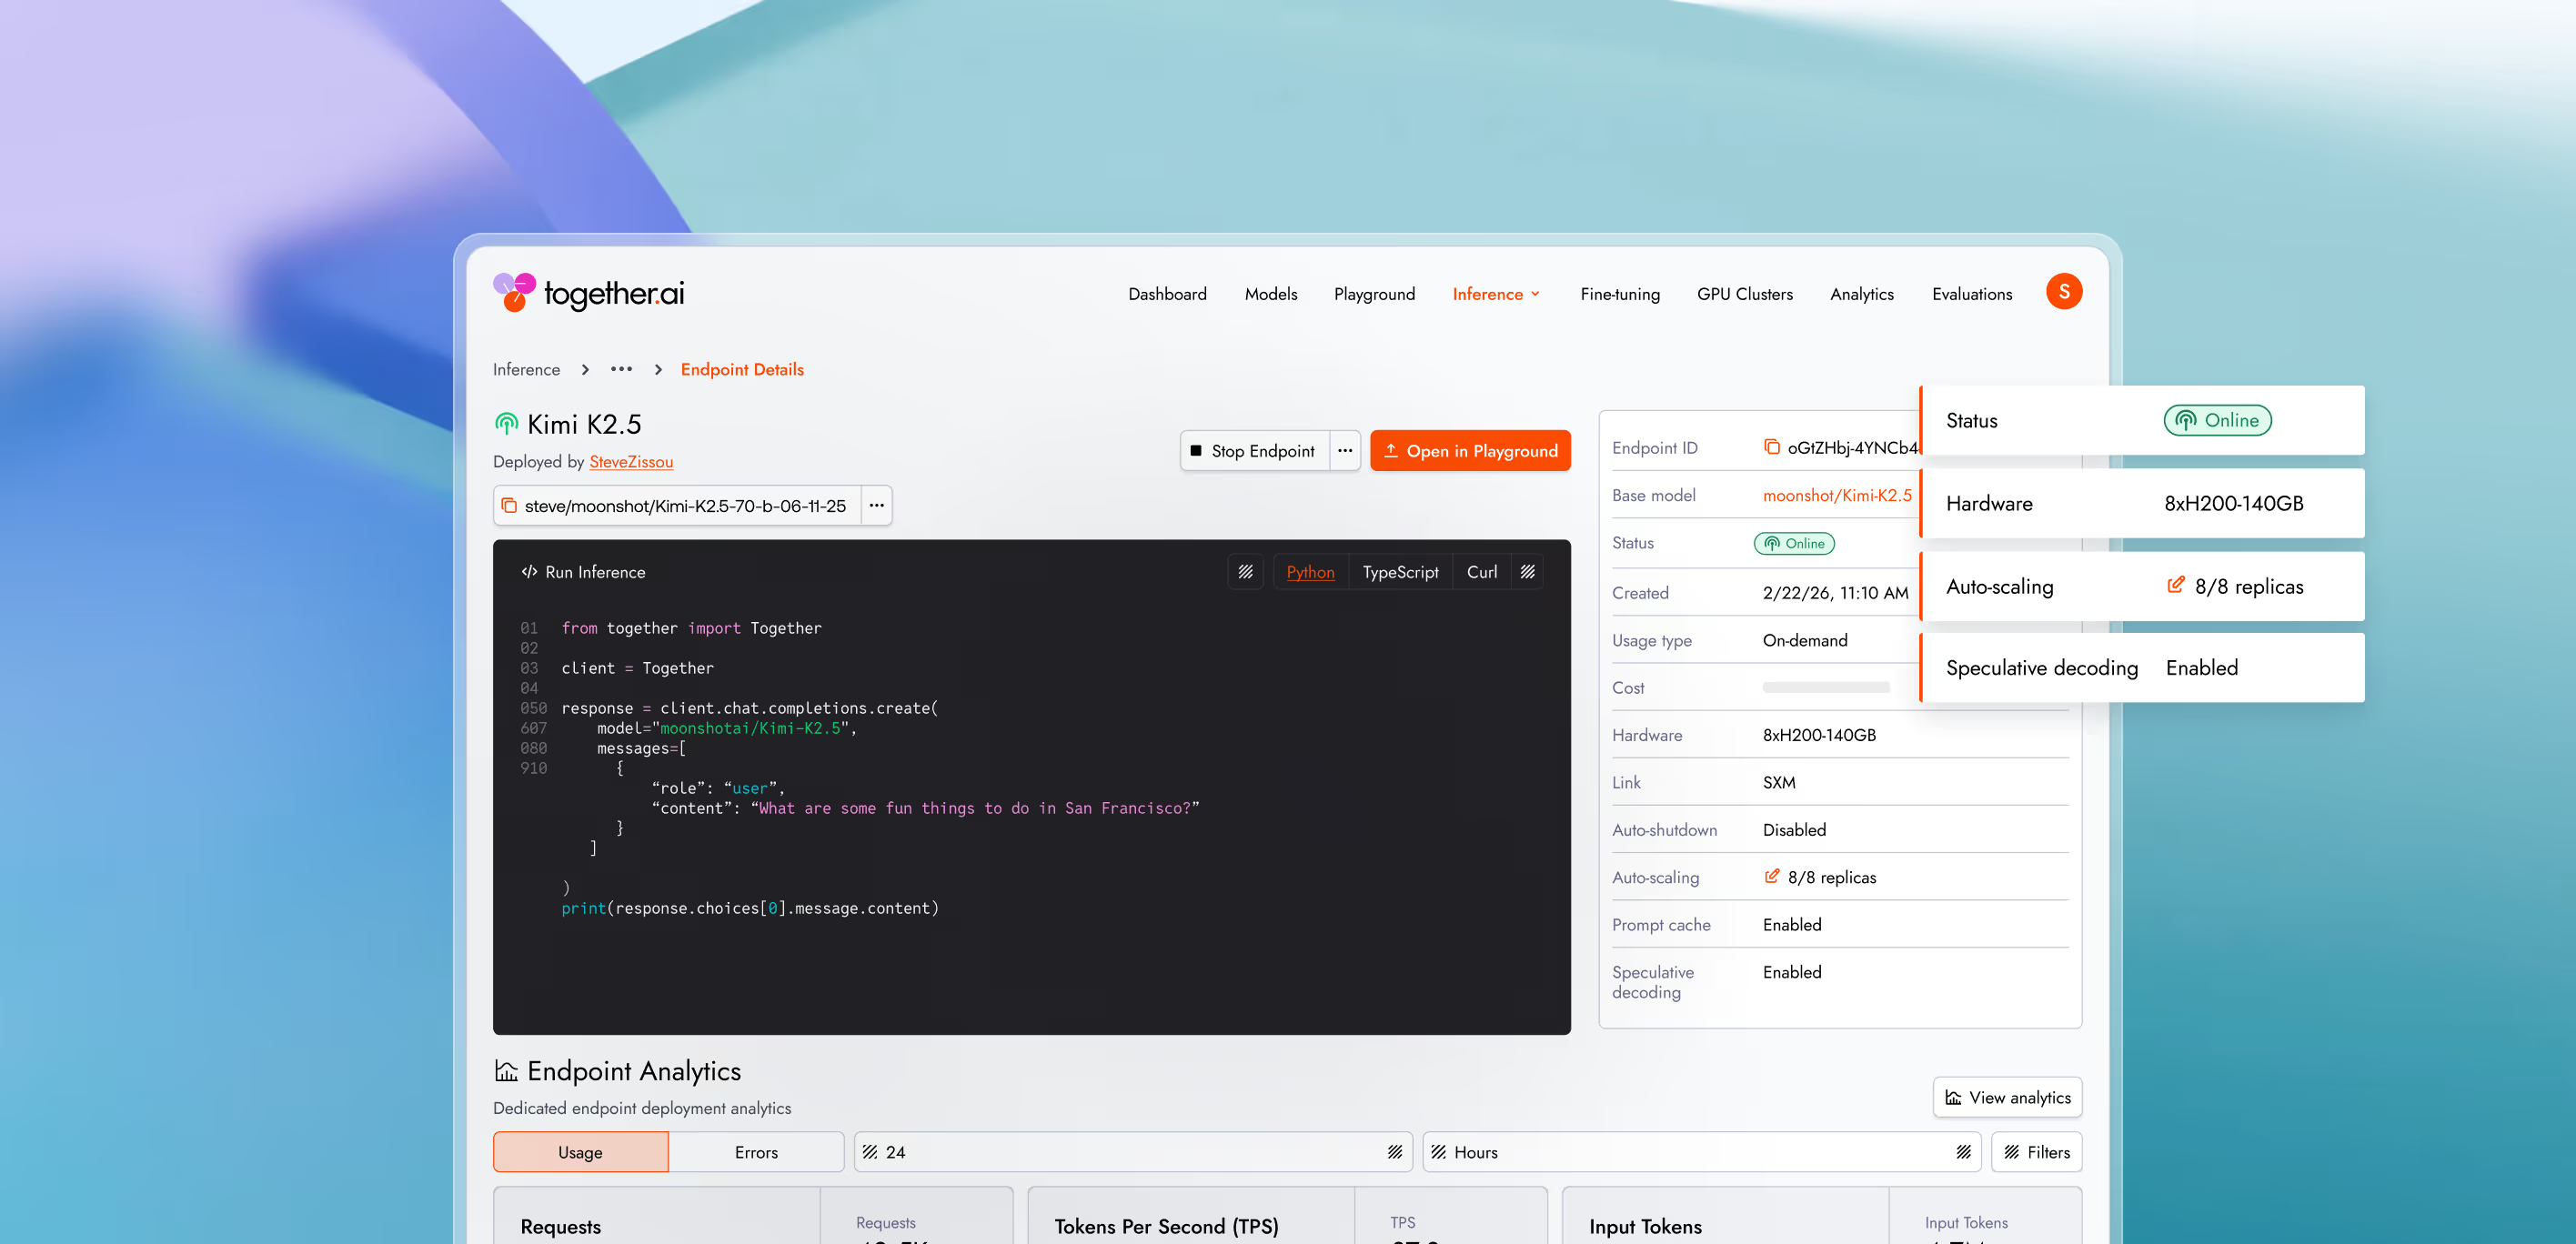
Why Dedicated Inference with Together AI?
Designed for production workloads that need consistent performance and operational control.
Built for production inference
Scale to thousands of GPUs for always-on, production inference deployments.
Industry-leading unit economics
We provide the fastest deployments, enabling best price-performance on top GPUs.
Powered by frontier AI systems research
We continuously roll out the latest innovations to keep your deployments running fast.
Research that ships
Our research team doesn't just publish. They build the optimizations that power every inference request.

 ATLAS

 CPD

 Megakernel

 ThunderKittens
Performance on DeepSeek V3.1 (Arena Hard)
- Atlas
- Static Speculator
- No Speculator


ATLAS performance
3.18x faster
ATLAS, our AdapTive-LeArning Speculator System, continuously learns from live traffic — outperforming static speculators and specialized hardware.
learn moreCPD improves sustainable QPS by 35-40%
- CPD
- Baseline


Together AI CPD vs 2P1D
+40% throughput
Long-context inference without the latency penalty. CPD (cache-aware prefill-decode disaggregation) separates warm and cold requests, cutting time-to-first-token and boosting throughput by up to 40%.
learn moreTime to first 64 tokens
- Megakernel (H100)
- Baseline (B200)


Megakernel vs baseline
Up to 3.6x faster
Megakernel fuses an entire model's forward pass into a single GPU kernel. Made using the ThunderKittens framework, Megakernel eliminates the idle gaps between operations that rob GPUs of their full potential.
learn moreBF16 all-reduce sum performance (on 8x NVIDIA B200s)
- PK
- NCCL


ParallelKittens vs NCCL
Up to 1.79x faster
ParallelKittens—an extension to ThunderKittens for multi-GPU workloads developed in collaboration with Stanford's Hazy Lab—cuts the synchronization overhead that large multi-GPU models pay on every single forward pass.
learn more
Build with leading models
Explore top-performing models across text, image, video, code, and voice.